Local AI Community Pulse: July 2026
A grounded reading of current Reddit and Hacker News discussions: where local models work today and why coding still needs guardrails.
News, tutorials, benchmarks, and case studies from the local AI ecosystem.
A grounded reading of current Reddit and Hacker News discussions: where local models work today and why coding still needs guardrails.
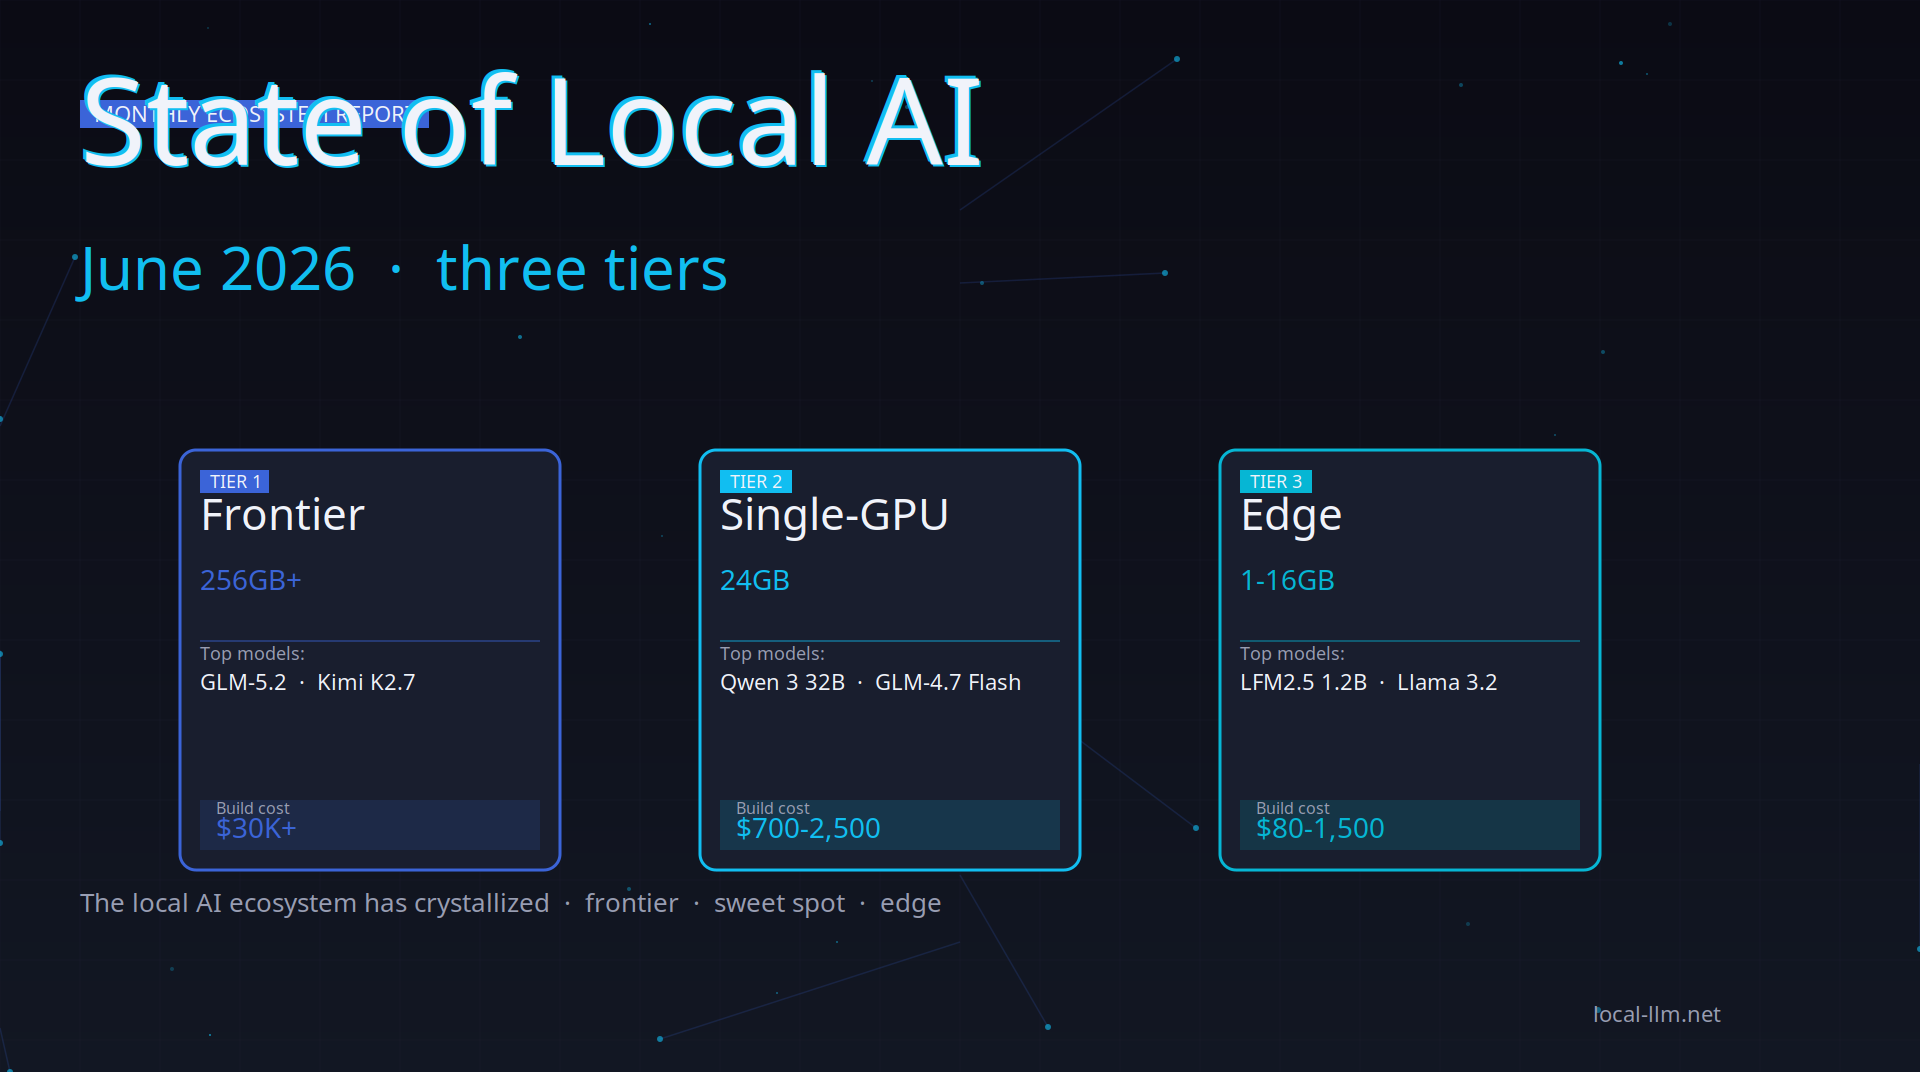
State of Local AI June 2026: the local AI ecosystem has crystallized into three tiers — frontier (256GB+), single-GPU (24GB), and edge (phones, SBCs).

Local AI release roundup for June 2026: GLM-5.2, Kimi K2.7 Code, minimax M2.7, and Qwen3-Coder 480B, with setup commands and VRAM requirements.
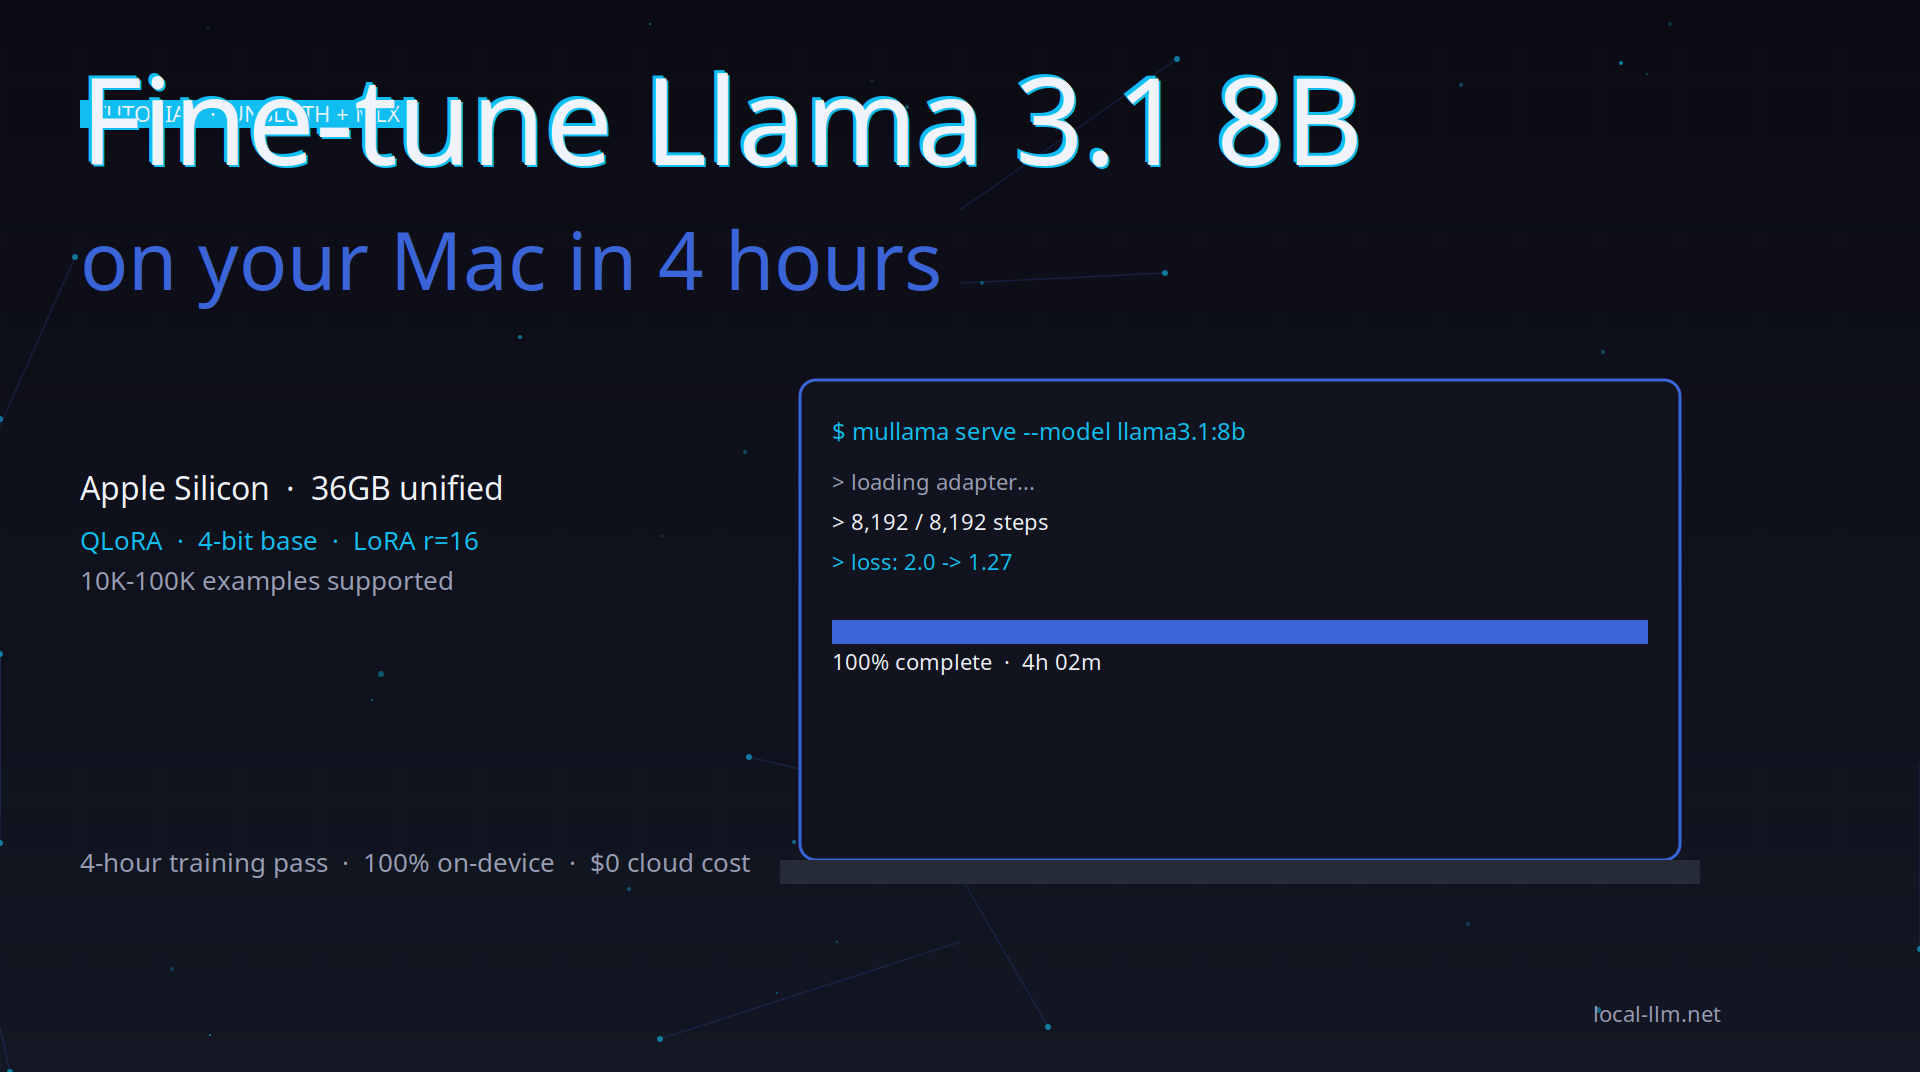
1 8B model on an Apple Silicon Mac in 4 hours using Unsloth, QLoRA, and MLX. Full setup walkthrough with code samples, dataset prep, and evaluation.
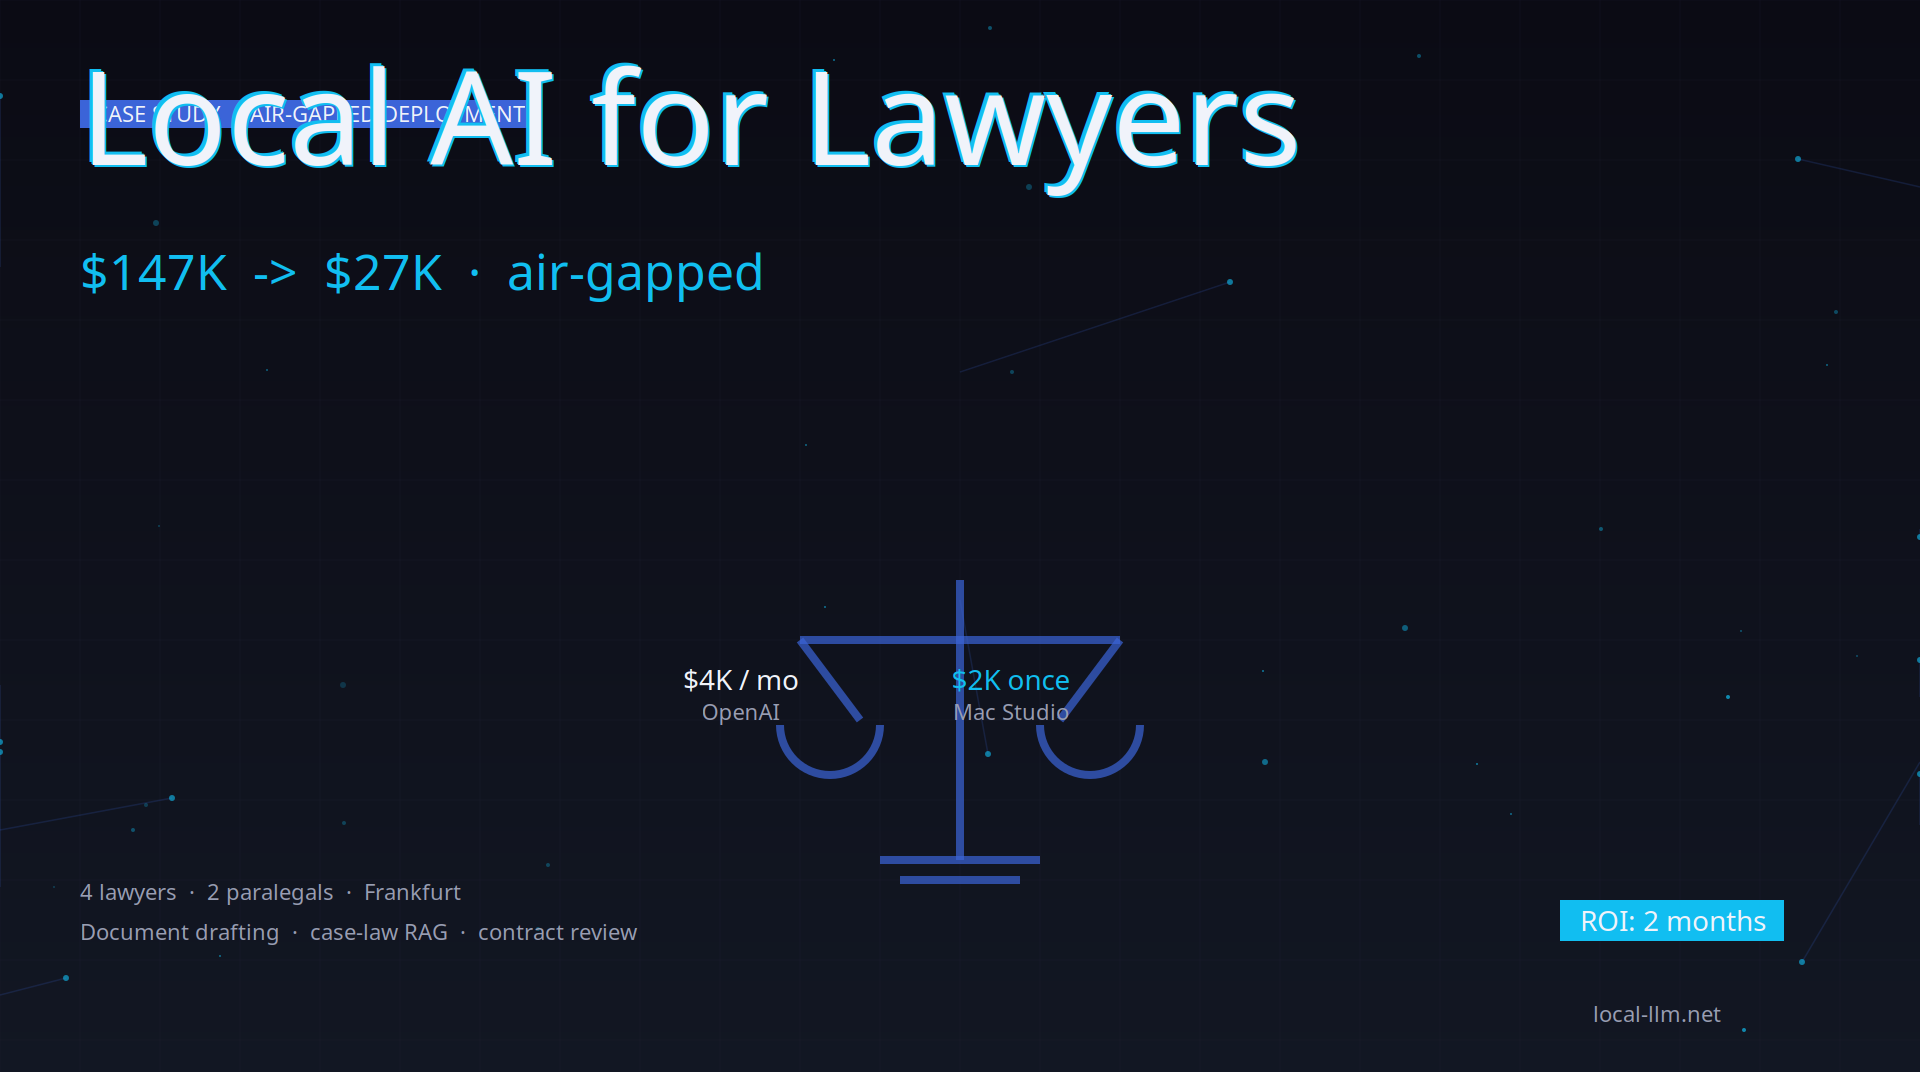
How a six-person law firm replaced most of a $4,000/month OpenAI bill with a $2,400 network-isolated local AI build and case-law RAG.

A step-by-step tutorial for building a fully offline AI assistant app for Android and iOS using Llamafu for on-device inference and Flutter for the UI.

An end-to-end walkthrough of fine-tuning a language model for customer support using Unsloth and QLoRA, from dataset prep to GGUF export.

Announcing local-llm.net — the community-driven guide to deploying AI locally. We cover the entire ecosystem because the local AI movement belongs to everyone.

A non-technical guide for fiction writers who want AI tools that respect creative freedom and privacy, using KoboldCpp and SillyTavern.

An honest, network-traffic-level audit of telemetry and data collection in Ollama, LM Studio, Jan, GPT4All, and Open WebUI in 2026.

An opinionated S/A/B/C/D tier ranking of every major local AI model across six categories: chat, coding, reasoning, creative writing, vision, and embeddings.

A step-by-step guide to building a RAG pipeline that works in production: Ollama for inference, ChromaDB for vectors, LangChain for orchestration.

A 30-day experiment ditching ChatGPT Plus for a fully local AI setup: what worked, what failed, exact costs, and an honest verdict.

Benchmarking the used RTX 3090 against the RTX 4090 and RTX 5090 for local AI inference and its 24GB VRAM at $500-800 used.

Deploy a multi-user ChatGPT alternative for your team using Open WebUI and Ollama: Docker, HTTPS, authentication, and cost analysis.

A comprehensive look at where local AI stands in 2026, from 70B models on consumer GPUs to mobile inference and what shifted since 2024.